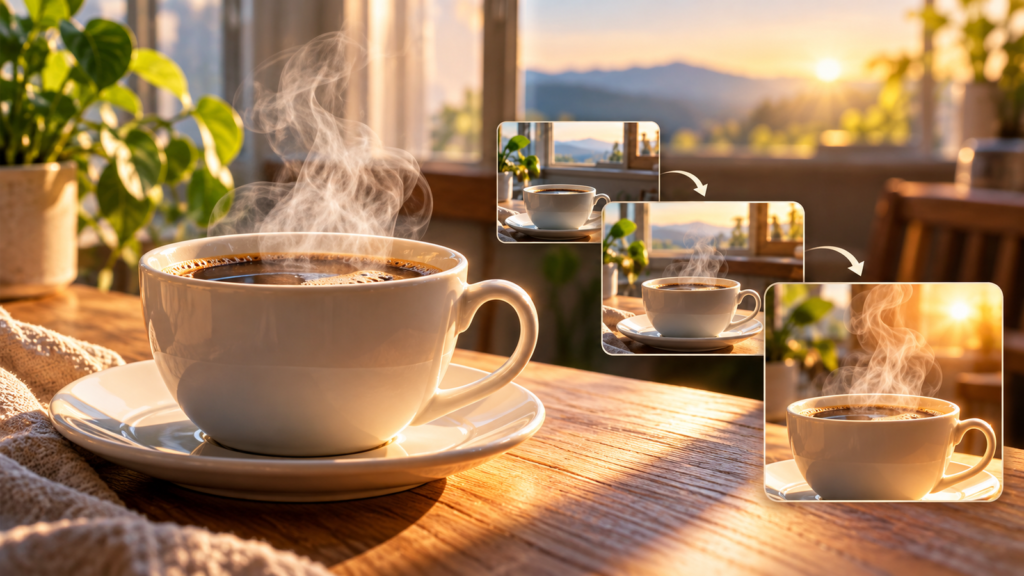
You ask “make a beautiful coffee video” and receive a cup that changes shape, a camera that races across the table, and light that changes direction. The idea seemed simple. What was missing was saying not only what exists in the scene, but what happens throughout it. Video adds time, movement, changing framing, continuity, and often editing and audio. To begin, think of a clear scene, generate a clip, observe the result, and adjust before planning the next scene.
What does creating AI video mean?
In a video generator, you describe a situation and receive a sequence of moving images. The tool interprets your instruction and makes decisions you left open: how the object moves, where the camera observes from, what appears in the background, and how the scene evolves. The first generation is a visual proposal to evaluate, not a guaranteed execution of every detail.
A still image needs to work in one frame. A video needs to keep making sense in subsequent frames. If the cup begins near the window, it should not change sides without reason. If the camera moves closer, the cup tends to occupy more space in the frame. If steam rises, the movement should look plausible throughout the clip. This temporal dimension is the main difference from the guide to creating AI images.
Some tools generate a clip directly from text, others animate an image, and some offer more than one path. Options change by product, model, plan, country, and date. Choose the workflow available in your account and treat the first result as material for review.
Text to video or image to video: what is the difference?
In text to video, you write a description, and the tool creates the visual and movement. “A bicycle on a wet street” describes an image. “A bicycle moves slowly along a wet street while reflections of lights appear on the pavement” adds action and time. The tool may interpret movement and details differently; check the clip instead of assuming literal obedience.
In image to video, an existing image serves as a starting point or reference when the platform offers it. You can ask for steam to rise, leaves to move, or the camera to approach. The image tends to guide composition, subject, light, and style, but does not promise perfect preservation of a face, object, setting, or physics. A good initial image reduces ambiguity; it does not remove the need to inspect the result.
Choose text to video when you are still exploring the scene’s appearance. Consider image to video when an approved composition already exists and you want to suggest movement. If you produce the base image with help from the IANautaLab image prompt generator, remember that it organizes image descriptions; video movement needs separate planning.
Start with a simple scene
Let us follow a cup of coffee on a wooden table beside a window. There are no people, dialogue, or several crossing objects. The initial version has a stationary cup, soft morning light, and slowly rising steam. It is a small scene but allows evaluation of subject, movement, camera, background, and light.
A short scene is usually easier to redo, compare, and combine with another. This does not define a universal duration: consult the tool’s options and choose a length sufficient for the action. In the first test, avoid asking for an entire multiscene video in one instruction. Separate the idea into clips when there is a sequence.
Before opening the generator, answer in one sentence: what should be visible, and what should change? For the coffee, the cup stays still and steam rises. This division already prevents mixing a static object with an agitated camera and several simultaneous events. Then decide the video’s destination. A horizontal article clip and a vertical phone-screen clip need different compositions; check your platform’s available aspect ratios.
How to write your first video prompt
Use these as support, without having to fill everything: subject, action, environment, framing, camera movement, movement within the scene, lighting, atmosphere, and restrictions. Add only what helps recognize a useful result. A long prompt with conflicting instructions can be less clear than a few concrete sentences.
Compare the vague request “create a coffee video” with this version: “A cup of coffee on a wooden table beside a window. Steam rises slowly. Soft morning light. Close-up. The camera moves closer slowly. A natural photographic look. No people or text.” Now we know the subject, location, what moves, how the camera behaves, and what should stay out. This reduces open choices without guaranteeing every instruction is followed.
If the first request still seems complex, begin with: “A stationary cup of coffee on a wooden table beside the window. Steam rises slowly. Soft morning light. Stationary camera.” This is the first prompt in the sequence. The next adds one decision at a time. Save the text used in each attempt to compare the alteration’s effect.
Describe movement without overcomplicating it
Video shows change. “A person in a square” gives the setting; “a person walks slowly across the square while leaves move in the wind” gives the action. In our example, the cup can remain motionless while steam rises. Saying who stays still and who moves helps avoid an unfocused animation.
Separate scene movement from camera movement. With a stationary camera, you observe steam rising in the same framing. With subtle steam and an approaching camera, the cup grows in the frame. Requesting both movements at once can work, but makes the cause of a strange result harder to identify. For a second test, use: “Keep the cup stationary, the morning light, and the slow steam. Have only the camera move closer gently.”
You do not need to master filmmaking terminology. “Stationary camera” is enough in many cases. “The camera moves closer” or “moves away” changes perceived distance. “Moves sideways” changes the lateral viewpoint. “Follows the bicycle” asks the camera to follow the subject. “Turns to show the window” describes a pan; “gradually points upward” describes a vertical tilt. Words such as pan, tilt, zoom, and dolly may appear in controls, but a direct description in English often communicates the initial intention better.
Also define speed and intensity when they matter. “Slow, subtle approach” creates a different expectation from “fast approach.” If the action should be small, say so. Still, actual speed needs checking in the generated file.
Control framing and camera
A close-up highlights the cup and steam but leaves less context. A medium shot shows part of the table and window. A wide view places the scene in its environment. Choose framing according to what the audience needs to notice. If the aim is observing steam, do not hide the cup in a wide room; if it is presenting the environment, leave space around it.
In video, framing may change during the action. An object can enter or leave the frame, and an approach can crop the cup’s handle. To avoid this, request space and describe the movement’s endpoint. A third prompt would be: “Medium shot of the whole cup beside the window. The camera approaches slowly, keeping the cup and handle fully in the frame until the end.” Check that the table edge and window remain coherent; the sentence does not replace visual review.
Light also changes how action is read. Soft morning, late afternoon, and studio light indicate different environments. In the example, light comes from the window and should remain coherent as the camera approaches. Avoid contradictory combinations, such as requesting morning light and sunset in one clip without a planned time passage. Atmosphere can be “calm and natural,” but concrete terms for light, color, and speed tend to help more than several vague adjectives.
Generate a clip, analyze, and adjust
Watch the entire first generation before asking for another. Ask: did the cup remain coherent? Does steam rise plausibly? Did the camera move as expected? Did the handle deform? Did an element appear or disappear? Did the background change too much? Did light change direction? Do speed and framing serve the goal?
Choose the biggest problem. If composition works but steam seems fast, do not rewrite the whole scene: “Keep the composition, cup, light, and camera. Change only the steam: slower and subtler movement.” This is the sequence’s fourth prompt and shows the adjustment method. If the tool allows editing the clip or starting from a previous version, use the available feature. If every generation starts from scratch, other aspects can change even with “keep” instructions. Save the good version and compare attempts.
After resolving movement, view the clip at its intended publishing size. A subtle monitor defect may become obvious on a vertical screen, or framing may lose information in a thumbnail. If nothing relevant is wrong, stop. More generation does not necessarily mean improvement.
How to correct common problems
Strange movement or unnatural physics: reduce action to a simple gesture, request slower speed, and generate another attempt. Object changing shape: simplify the scene, reduce simultaneous movements, and consider a clear starting image if the service accepts it. Elements appearing or disappearing: remove secondary objects from the request and check that the background is not too busy.
Camera too fast: request a stationary camera or slow approach. Unstable background: describe which parts should stay in place and avoid several camera changes. Inconsistent character: test references or continuity controls only when available, and review each clip; perfect identity is not assumed.
Illegible text: if a word must be exact, consider inserting it during editing and check letter by letter in the final result. Overloaded clip: remove actions or split them into scenes. These changes increase clarity but do not guarantee correction. When an attempt repeatedly fails, changing approach is usually more useful than adding more prompt adjectives.
How to create several scenes with some consistency
After the first clip, you can plan three scenes: the cup beside the window, a close approach to the steam, and a wider view of the table. Write each scene’s purpose before generating. Continuity is harder than a single clip: the cup may change shape, the table color, or light direction between scenes.
Repeat the important characteristics: white ceramic cup, wooden table, window on the left, soft morning light, and a natural photographic look. In compatible tools, a reference image, saved frame, extension option, or editing features may help. Google’s Flow documentation, for example, describes visual references, frames, and clip assembly; available features depend on the model and account. Do not assume every platform has a seed, extension, or identity preservation.
A fifth prompt, for image to video, would be: “Use this image of the cup beside the window as the initial frame. Preserve the composition as a reference. Animate only the steam rising slowly; stationary camera and stable morning light.” This is not a promise of perfect preservation: compare each important frame with the base image. For the next clip, use consistent appearance instructions and, if possible, an authorized reference. Then order the scenes in the editor and cut points where continuity breaks.
Which AI video tools exist?
There is no universal choice. Before selecting a service, check whether it accepts text, images, or both; which models and formats your account offers; how credit consumption works; whether there is a watermark; and which terms apply to your project. Prices, durations, resolution, and regional access change, so consult current screens and documentation instead of following numbers from an old tutorial.
Google Flow: the official video-creation help describes clips from text, frames, and references. The editing and scenes help documents clip organization and editing functions. It is a useful example for trying references and assembling a sequence. Before use, check the active model’s features, plan, and availability in your region.
Adobe Firefly: the official generation and editing documentation shows video creation from text and use of images as initial or final frames in the described environment. It is an option to investigate if you prefer a base image and visual controls. Check which functions your account has and how the file will be exported.
Runway: the official image-to-video guide explains that the image guides composition, subject, light, and style, while text guides movement and temporal progression. It is a clear example of animating an image. Check the selected model and current plan conditions before starting; functions vary between versions.
These examples explain workflows, not a ranking. Do a small test with a similar scene, compare the control the tool actually offers, and choose one that serves the video’s destination.
Audio, text, and final editing
A visual clip is not necessarily a finished video. Depending on service and model, generation may include audio or require separate stages for voice, music, and effects. Check what your tool delivered. If the project needs narration, you can plan the text, record or generate the voice in an appropriate stage, and synchronize it in editing. Do not assume every generator automatically produces synchronized audio.
For a title, caption, product name, or call to action, review every word. When text must be exact, adding it in the editor usually provides more control than depending on the generated scene. This does not mean no generator can write words; it means editorial precision requires checking.
During assembly, cut weak passages, order clips, adjust each scene’s beginning and end, balance audio, add text, and export in the channel’s accepted format. Transitions can be subtle. A sequence of good clips in an understandable order usually works better than a long clip with too many events.
Care before publishing an AI-generated video
Use your own or authorized images and videos as references. Avoid sending private material when a generic description solves the task. Check platform rules and, for commercial use, current applicable terms. This is a practical check, not a legal conclusion.
If the video shows a real person, news, product, or factual demonstration, do not let the audience believe a generated scene documents something that happened. Review faces, brands, speech, text, and context. A convincing video can convey a false claim even without an explicit caption. Retain a person responsible for final review.
Create your first video step by step
First, choose one observable action: steam rising from the cup. Second, decide whether to begin from text or an authorized base image. Third, write subject, environment, action, and camera in direct language. Fourth, choose available format and duration options with the destination in mind. Fifth, generate a clip and watch to the end, including on a phone. Sixth, record the biggest defect and adjust only that variable. Seventh, save the working version.
If you want a sequence, write the next scene separately and repeat visual details that must continue. Use references or frames when your tool offers them; then combine clips and review audio, text, and transitions. The Creating with AI hub brings together related content. The first exercise’s goal is not a complete film: it is learning to control a scene, recognize what changed, and decide the next adjustment clearly.